You Are Using the
Wrong Model for the Job
Lessons from two opposite bugs that turned out to be the same mistake. Drawn from building SembleOps, a personal operations ensemble.
💡 Pin this to keep notes while reading!
📝 Show Notes & Ideas▼
The model did not technically fail, which was the core issue.
It returned an HTTP 200, tokens were billed, and the system marked the job as a success. But the answer was completely blank.
Then I ran into the opposite problem. A simple yes-or-no routing question came back with four paragraphs of reasoning, a summary, and a closing sentence. It was technically correct, but operationally it was terrible: slow, expensive, and way more output than needed.
These seemed like unrelated failures, but they were actually caused by the same mistake.
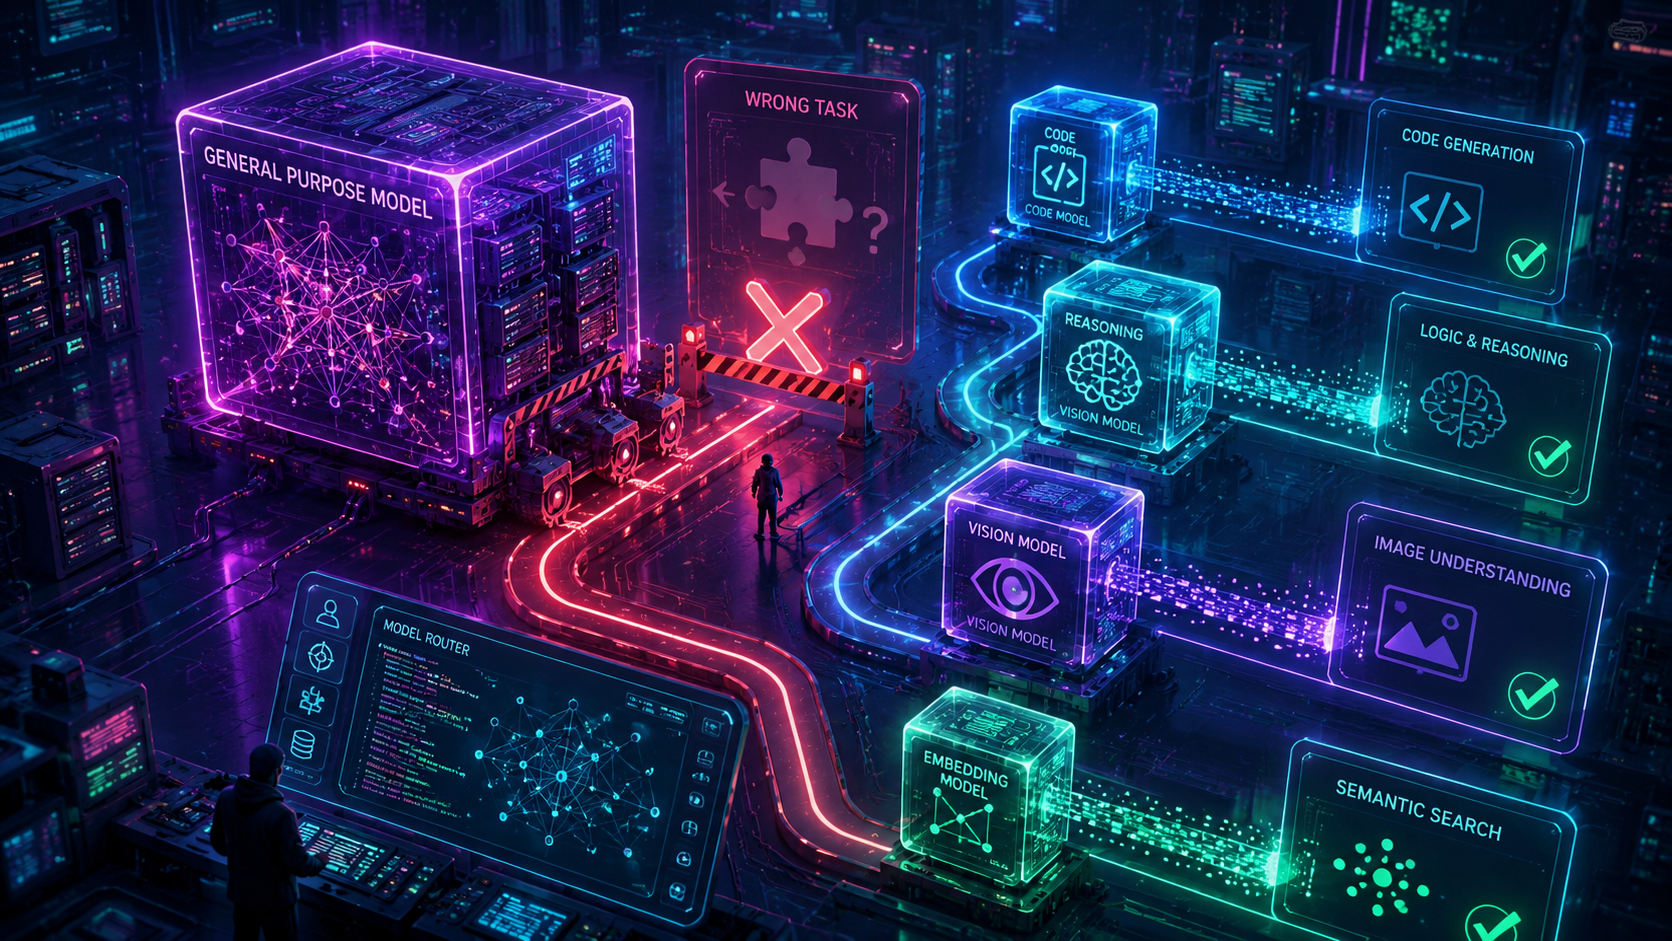
In both cases, I picked the wrong model for the job. One model didn't have enough resources to answer, while the other was too powerful for a task that barely needed any thought.
When your model choice and output length don't fit the task, your system pays the price in cost, speed, and user experience.
Failure One: The Reasoning Model That Writes Nothing
Every chat completion has a limit on how many tokens it can generate. With older models, you set this using max_tokens. For reasoning models, you use max_completion_tokens. These settings look similar, but they aren't, the difference is what each one actually limits.
max_tokens caps:
The visible answer.
max_completion_tokens caps:
The thinking plus the visible answer.
Reasoning models use tokens to think before they respond, and those tokens come from the same budget you set. These thinking tokens don't show up in the response, but you still get billed for them, and they're used up first.
So if you set a 400-token cap, you won't get a 400-token answer. The model might use 380 tokens just to think, leaving only 20 for the answer. Sometimes you get a cut-off fragment, but often you get nothing at all because it never gets to the answer.
The Failure Signature
The finish_reason will be 'length', usage will show tokens spent, and message.content will be empty. Billed tokens, blank answer, and your system calls it a success.
If you set the cap too low on a reasoning model, you don't get a short answer. You get no answer at all, but it still looks like a success. My mistake made sense: I set a low cap because I wanted a short response, thinking the cap would control the length. That works on a normal model, but on a reasoning model, it prevents the answer from being written at all.
Failure Two: The Powerful Model That Overwrites
Now for the opposite problem, which is something almost everyone does without realizing it.
A high-reasoning model like Opus 4.8 is great for tough problems. But if you use it for something simple, it still goes through its full process. Ask it whether a message is a task or a question, and it will consider edge cases you never had, weigh different interpretations, and give you a detailed answer when you only needed one word. The answer is right, but it's slow, and you pay for every token it uses to think and write.
This is a quieter and more expensive failure because nothing seems broken. The output looks fine, but it's much more than the task needed, created by a pricier model than necessary, and it takes longer than the task allows. If you do this for every call in your system, your product feels slow and your costs go up for no obvious reason.
It feels safe to always use the best model, but this is the biggest reason for wasted money and slowdowns in AI products today. These tasks need a direct answer, not a college essay of an explanation.
The Unifying Rule: Size the Model and the Length to the Task
Before you make any calls, ask yourself two specific questions:
1. Does this task need reasoning at all?
For things like routing, classification, extraction, tagging, or short replies, the answer is no, these are pattern-matching jobs. Use a fast, inexpensive model, or set reasoning to a minimum. Save the deep-reasoning models for truly hard, multi-step problems where accuracy is worth the extra time and cost.
2. How long should the answer really be?
A verdict only needs one line. A research packet might need a whole page. These are different tasks and shouldn't use the same settings.
Most systems do not consider these questions and instead rely on a single large model with default settings for all tasks. This approach simultaneously deprives complex tasks of necessary resources and overwhelms simple tasks with excessive output.
What I Changed
Here's how I applied this in a side project I built called SembleOps: a coordinator named Marco Maestro, my router, routes every request, and a group of specialist agents handles the actual work.
Routing uses minimal reasoning
When Marco decides who should handle a request, it's just classification, not problem-solving. So the routing call sets reasoning to minimal and skips the deep reasoning path:
// Routing is classification, not problem-solving: skip deep reasoning.
...(opts.minimalReasoning &&
  model.startsWith("gpt-5") &&
  { reasoning_effort: "minimal" }),
The Result
That single change took routing from about 33 seconds on a heavier CLI runtime down to just 2 seconds. The task never needed deep reasoning, so removing it dropped the cost and made everything faster.
Token caps are runaway protection, not length control
I moved the length target into the prompt, where I specify a word range and structure. The cap is only there to stop a real runaway, and for reasoning models, I add extra room so thinking tokens don't use up the whole budget before the answer.
// Reasoning models spend thinking tokens from the same budget, so a
// tight cap yields an EMPTY completion. The cap here is runaway
// protection only; the real length target travels in the prompt.
...(opts.maxCompletionTokens &&
  (model.startsWith("gpt-5")
    ? { max_completion_tokens: opts.maxCompletionTokens + 1500 }
    : { max_tokens: opts.maxCompletionTokens })),
This distinction is important: reasoning models require additional token allocation, whereas older models only need a straightforward cap. Although the objective remains consistent, token budgets must be tailored to the operational characteristics of each model.
Empty output counts as a failure, not a success
This is the rule I'd give anyone using reasoning models: if the model returns an empty result, don't pass it along as if it worked. Treat it as a failed call and try the next model instead.
const text = data.choices?.[0]?.message?.content ?? "";
if (text.trim().length === 0) {
  // Never report an empty completion as success (a length-capped
  // reasoning model does exactly this) fall through to the next model.
  lastError = `${model}: empty completion (finish_reason ${
    data.choices?.[0]?.finish_reason ?? "unknown"
  })`;
  continue;
}
A blank result presented to a user is more problematic than an explicit error. An error at least indicates a failure, whereas a blank output provides no feedback.
Instead of limiting output with a low cap, agents get a word budget and a required structure in the prompt. There's also an appendix rule: anything under an "Appendix" heading collapses in the UI and doesn't count against the budget. This way, answers are short and easy to read by default, but users can get more detail if they want, without using the token cap to limit output.
The Lessons Are Portable to Any Stack
- max_tokens and max_completion_tokens are not the same. One limits just the answer, the other limits both thinking and the answer. Make sure you know which model you're using.
- A low cap on a reasoning model gives you empty output, not a short one. If you want a short answer, ask for it in the prompt and give the cap some extra room.
- An empty completion means failure. Never treat it as a success. Detect it, log the finish_reason, and either retry or move on to the next model.
- Not every task needs a reasoning model. For routing, classification, and extraction, use a fast model or minimal reasoning. Save the heavy models for the tough problems.
- Defaulting to the most advanced model is the most expensive habit in AI development. Model selection should be based on task complexity rather than concerns about output quality.
- Control answer length by agreement, not by cutting it off. Giving a word range and structure in the prompt works better than a token cap for anything people need to read.
- Cost and speed are design choices, not accidents. Every call is a decision about how much intelligence the task really needs. Make that choice on purpose.
The Mindset That Ties It All Together
A token cap is there for safety, not for control. A powerful model is a tool, not the default.
Choose the smallest model that does the job, tell it how long the answer should be, and never accept an empty result as a success.
Two opposite bugs, one mistake. Size the intelligence to the task, and both of them disappear.
The model did not technically fail, which was the core issue.
It returned an HTTP 200, tokens were billed, and the system marked the job as a success. But the answer was completely blank. Then I hit the opposite problem: a simple yes-or-no routing question came back with four paragraphs of reasoning, a summary, and a closing sentence. Both failures had the same cause. I picked the wrong model for the job.
Failure One: The Reasoning Model That Writes Nothing
Older models cap output with max_tokens. Reasoning models use max_completion_tokens, and the difference matters:
- •
max_tokenscaps the visible answer. - •
max_completion_tokenscaps the thinking plus the visible answer.
Reasoning models think before they respond, and those thinking tokens come out of the same budget, first. Set a 400-token cap and the model might spend 380 tokens thinking, leaving 20 for the answer. Often it never gets to the answer at all. The finish_reason is 'length', usage shows tokens spent, and message.content is empty.
The Trap
I set a low cap because I wanted a short response. That works on a normal model. On a reasoning model, it prevents the answer from being written at all, and it still looks like a success.
Failure Two: The Powerful Model That Overwrites
Use a high-reasoning model like Opus 4.8 for a trivial question and it still runs its full process: weighing edge cases you never had, considering interpretations, writing a detailed answer when you needed one word. The output looks fine, so nothing seems broken. But it's slower and more expensive than the task allowed, on every single call. Multiply that across a system and your product feels slow and your bill climbs for no obvious reason.
The Unifying Rule
Before you make any call, ask two questions:
- 1. Does this task need reasoning at all? Routing, classification, extraction, tagging: no. Use a fast model or minimal reasoning. Save the deep-reasoning models for genuinely hard, multi-step problems.
- 2. How long should the answer really be? A verdict needs one line. A research packet might need a page. Different tasks shouldn't share the same settings.
In my side project SembleOps, applying this took routing from about 33 seconds down to 2. Token caps became runaway protection only, length targets moved into the prompt, and empty completions now count as failures that fall through to the next model.
The Mindset:
A token cap is there for safety, not for control. A powerful model is a tool, not the default. Choose the smallest model that does the job.
Danny's Quick Takes:
- →max_tokens and max_completion_tokens are not the same. One caps the visible answer. The other caps thinking plus the answer, and reasoning models spend the thinking tokens first.
- →A low cap on a reasoning model gives you nothing, not something short. The model burns the budget thinking, returns an empty answer, and still reports HTTP 200. It looks like a success.
- →Empty completion = failure. Detect it, log the
finish_reason, and retry or fall through to the next model. Never pass a blank result to a user. - →Not every task needs a reasoning model. Routing, classification, and extraction are pattern-matching jobs. Minimal reasoning took my routing call from 33 seconds down to 2.
- →Control length in the prompt, not the cap. Give a word range and a structure. The token cap is runaway protection, not a steering wheel.
The Bottom Line:
Choose the smallest model that does the job, tell it how long the answer should be, and never accept an empty result as a success. A token cap is there for safety, not for control, and a powerful model is a tool, not the default.